Monday, January 18, 2010

多核、多CPU环境下的程序开发

要点:

1. 任务划分,这点最关键。

1.1 对任务做充分理解,分清是数据密集型应用还是计算密集型计算。如果是数据密集型应用,则应该尽量提高总线的使用率(FSB, QPI等);而计算密集型应用,则应该提高CPU的使用率。

1.2 找出尽可能多的并行部分(任务分解,数据分解);

1.3 分析这些并行部分的特点,组成合适的并行任务


2. 资源本地化。尽量使所有的线程可以无条件地并发。

2.1 对于Non-Uniform Memory Access(NUMA) 结构的系统(多CPU的server,带QPI技术的intel多核处理器,带HyperTransport技术的AMD多核处理器),注意内存的分配位置。

3.充分利用Intel/AMD CPU的硬件特征。

3.1 充分利用CPU的本地cache
3.2 防止cache伪共享
3.3 系统内核同步?
3.4 数据密集型计算,注意NUMA特性.

可用技术:
Boost::thread
OpenMP
Intel Thread building block
MPI
语言内建的并行支持 (C#,Java等)

Monday, November 2, 2009

Characters Encoding

  • ISO 646
-- ISO 7-bit coded character set for information interchange, a simple extension of ASCII

  • ISO/IEC 8859
ISO/IEC 8859 is a joint ISO and IEC series of standards for 8-bit character encodings. The series of standards consists of numbered parts, such as ISO/IEC 8859-1, ISO/IEC 8859-2, etc.

  • GB 2312
GB2312 (1980) has been superseded by GBK and GB18030, which include additional characters.
Characters in GB2312 are arranged in a 94x94 grid, The value of the first byte is from 0xA1-0xF7 (161-247), while the value of the second byte is from 0xA1-0xFE (161-254)

To map the code points to bytes, add 160 (0xA0) to the 1000's and 100's value of the code point to form the high byte, and add 160 (0xA0) to the 10's and 1's value of the code point to form the low byte.

For example, if you have the GB2312 code point 4566 ("foreign,"), the high byte will come from 45 (4500), and the low byte will come from 66 (0066). For the high byte, add 45 to 160, giving 205 or 0xCD. For the low byte do the same, add 66 to 160, giving 226 or 0xE2. So, the full encoding is 0xCDE2.

  • GBK
The GBK character set was defined in 1993 as an extension of GB2312-80, while also including the characters of GB13000.1-93 through the unused codepoints available in GB2312. Hence GBK is upward compatible with GB2312.

A character is encoded as 1 or 2 bytes. A byte in the range 00¨C7F is a single byte that means the same thing as it does in ASCII.

A byte with the high bit set indicates that it is the first of 2 bytes. Loosely speaking, the first byte is in the range 81–FE (that is, never 80 or FF), and the second byte is 40–FE for some areas and 80–FE for others

  • GB18030
GB18030 can be considered a Unicode Transformation Format that maintains compatibility with a legacy character set. GB18030 is a superset of ASCII and can represent the whole range of Unicode code points; in addition, it is also a superset of GB2312. GB18030 also maintains compatibility with Windows Codepage 936, sometimes known as GBK

Unicode
The Unicode Standard consists of a repertoire, an encoding methodology and set of standard character encodings etc.
The Unicode Consortium, the nonprofit organization that coordinates Unicode's development, has the ambitious goal of eventually replacing existing character encoding schemes with Unicode and its standard Unicode Transformation Format (UTF) schemes,
Unicode can be implemented by different character encodings. The most commonly used encodings are UTF-8 (which uses 1 byte for all ASCII characters, which have the same code values as in the standard ASCII encoding, and up to 4 bytes for other characters), the now-obsolete UCS-2 (which uses 2 bytes for all characters, but does not include every character in the Unicode standard), and UTF-16 (which extends UCS-2, using 4 bytes to encode characters missing from UCS-2).

ISO 10646
ISO 10646 and Unicode have an identical repertoire and numbers. The difference between them is that Unicode adds rules and specifications that are outside the scope of ISO 10646. ISO 10646 is a simple character map, an extension of previous standards like ISO 8859. In contrast, Unicode adds rules for collation, normalization of forms, and the bidirectional algorithm for scripts

  • UTF-8
The UTF-8 encoding is variable-width, ranging from 1–4 bytes. Each byte has 0–4 leading 1 bits followed by a zero bit to indicate its type

  • UTF-16
For characters in the Basic Multilingual Plane (BMP) the resulting encoding is a single 16-bit word. For characters in the other planes, the encoding will result in a pair of 16-bit words, together called a surrogate pair.

  • UCS2
The UCS-2 encoding form is identical to that of UTF-16, except that it does not support surrogate pairs and therefore can only encode characters in the BMP range U+0000 through U+FFFF

IANA character-sets
http://www.iana.org/assignments/character-sets

Character encoding(WikiPedia)
http://en.wikipedia.org/wiki/Charset

Sunday, October 18, 2009

Sip

rfc2543 -> Obsoleted by: 3261, 3262, 3263, 3264, 3265

rfc3261: SIP: Session Initiation Protocol

Monday, August 24, 2009

防护等级介绍

● 防护等级介绍
IP是国际用来认定防护等级的代号,IP等级由两个数字所组成,第一个数字表示防尘,第二个数字由表示防水,数字越大表示其防护组合越佳。

防尘等级

号码 防护程度 定义
0 无防护 无特殊的防护
1 防止大于50mm之物体侵入 防止人体因不慎碰到内部零件
2 防止大于12mm之物体侵入 防止手指碰到内部零件
3 防止大于2.5mm之物全侵入 防止工具,电线或限制范围的物体侵入
4 防止大于1.0mm之物体侵入 防止的蚊蝇、昆虫或物体侵入
5 无法完全防止灰尘侵入 侵入灰尘量不会影响灯具正常运作
6 防尘 完全防止灰尘侵入

 防水等级

号码 防护程度 定义
0 无防护 无特殊的防护
1 防止滴水侵入 防止垂直滴下之水滴
2 倾斜15度时防止滴水侵入 当物体倾斜15度时,仍可防止滴水
3 防止喷射的水侵入 防止雨水、或垂直入夹角小于50度方向
4 防止飞溅的水侵入 防止各方向飞溅而来的水侵入
5 防止大浪的水侵入 防止大浪或喷水孔急速喷出的水侵入
6 防止大浪的水侵入 在一定时间和水压的条件下仍正常运作
7 防止侵水的水侵入 无期限沉没在一定水压的条件下正常运作
8 防止沉没的影响

Thursday, December 25, 2008

Adjust the performance of WinPcap

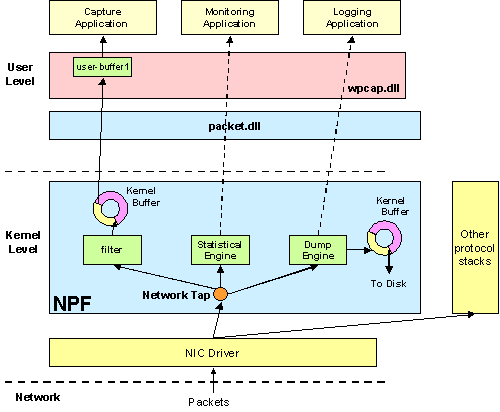
1. WinPcap archtechure


2. Performance related function.

2.1 int pcap_setuserbuffer(pcap_t *p, int size); // set the user-buffer size, in bytes,

2.2 int pcap_setbuff (pcap_t *p, int dim); // set the kernel-buffer size, in bytes

2.3 int pcap_setmintocopy (pcap_t *p, int size);//

2.4 send multi-packages to the kernel at once

pcap_send_queue* pcap_sendqueue_alloc ( u_int memsize );
void pcap_sendqueue_destroy ( pcap_send_queue * queue ) ;
int pcap_sendqueue_queue ( pcap_send_queue * queue, const struct pcap_pkthdr * pkt_header, const u_char * pkt_data );
u_int pcap_sendqueue_transmit ( pcap_t * p, pcap_send_queue * queue, int sync )

Monday, November 10, 2008

Some algorithms for RSA


1. Euclid Algorithm: GCD(a, b) = GCD(b, a % b)

1.1 a fast gcd implimetation:

1.2 calculate d for equation: (e*d)%( (p-1)(q-1) ) == 1
e * d = 1 (mod R) // (pre-condition gcd(e, R) = 1)
==> e * d = R * k + 1
==> e * d - R * k = e * d + R * K = 1 = gcd(e, R)
==> R * d1 + (e%R) * K1 = gcd(R, e%R) // (replace: e=>R, R=> e%R)
==> e * d + R * K = R * d1 + (e%R) * K1 // ( gcd(e, R) == gcd(R, e%R)
==> e * d + R * K = R * d1 + (e - [e/R]*R) * K1 = R * d1 + e * K1 - [e/R]*R * K1 = e * K1 + R * (d1 - [e/R]) * K1
==> d = K1, K = d1 - [e/R] * K1


#include < iostream >

bool Euclid(unsigned long& d, unsigned long e, unsigned long R)
{
unsigned long m=R, t1,t2;
unsigned long k=1,k1=0;
d = 0;

while(e!=1)
{
if(e==0) return false;
t1=R/e;
t2=R%e;

if( d < t1*k ) {
k1 = (t1*k - d) % m;
if(k1 > 0) { k1 = m - k1; }
} else {
k1 = d - t1*k;
}
k1= (d>=t1*k) ? (d - t1*k) : (d + m - t1*k);
d=k;
k=k1;

R=e;
e=t2;
}
d = k;
return true;
}
main()
{
unsigned long a,b,c;

std::cout << "Input a:";
std::cin >> a;
std::cout << "Input b:";
std::cin >> b;

if(Euclid(c, a,b))
std::cout << "( " << a << " * " << c << ") % " << b << " == 1 " << std::endl;
else
std::cout << "gcd(" << a << ", " << b << ") != 1" << std::endl;
}


2. Prime detect


Fermat小定理:
若n是素数,则对所有1≤a≤n-1的整数a,有a^(n-1)mod n=1;
该定理的逆否命题也成立,即a^(n-1)mod n!=1,则n为合数;
该定理的逆命题不一定成立, 如当a=4,n=15时,4^14mod15=1,但是4不是素数而是合数。


如果满足a^(n-1)mod n=1,则n较大概率为素数。我们把那些使得n原本为合数而被看成素数的a叫做伪证据,n为伪素数。


强伪素数:
设n是一个大于4的奇整数,s和t是使得(n-1)=(2^s)*t的正整数,其中t为奇数,设B(n)是如下定义的整数集合:
a属于集合B(n)当且仅当2≤a≤n-2且
1: a^tmodn=1,或
2: 存在整数i,0 <= i < s 满足a^((2^i)*t) mod n=n-1


当n为素数时, 任意a在2和n-1中,均有a属于集合B(n);
当n为合数时,若a属于集合B(n),则称n为一个以a为底(基)的强伪素数,称a为n素性的强伪证据。
n为素数,说明它对所有底均为强伪素数


typedef unsigned long T1;
typedef unsigned long long T2;

bool btest(const T1 a, const T1 n)
{
if( !(n&0x01) ) return false; // n is a Odd

// (n-1)= t*(2^s), t is a odd
T1 s = 0, t = n-1;
do {
++s;
t >>= 1;
} while( !(t&0x01) );

// a^t mod n = 1
T2 tmp = 1;
for(unsigned int i=0; i < t; i++) {
tmp = (tmp * a) % n;
}

if(tmp == 1 || tmp == n - 1) return true;

//a^((2^i)*t) mod n = n-1
T1 i = 1;
for(; i < s; ++i) {
tmp *= tmp;
tmp %= n;
if(tmp == n - 1) return true;
}

return false;
}

Wednesday, November 5, 2008

MD5 algorithm C++ implementation

/* md5.c - MD5 Message-Digest Algorithm
 * Copyright (C) 1995,1996,1998,1999,2001,2002,
 *               2003  Free Software Foundation, Inc.
 *
 * This file is part of Libgcrypt.
 *
 * Libgcrypt is free software; you can redistribute it and/or modify
 * it under the terms of the GNU Lesser General Public License as
 * published by the Free Software Foundation; either version 2.1 of
 * the License, or (at your option) any later version.
 *
 * Libgcrypt is distributed in the hope that it will be useful,
 * but WITHOUT ANY WARRANTY; without even the implied warranty of
 * MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
 * GNU Lesser General Public License for more details.
 *
 * You should have received a copy of the GNU Lesser General Public
 * License along with this program; if not, write to the Free Software
 * Foundation, Inc., 59 Temple Place - Suite 330, Boston, MA 02111-1307, USA
 *
 * According to the definition of MD5 in RFC 1321 from April 1992.
 * NOTE: This is *not* the same file as the one from glibc.
 * Written by Ulrich Drepper , 1995.
 * heavily modified for GnuPG by Werner Koch
 */

#ifndef _MD5_H_
#define _MD5_H_

#include
#include
#include
#include "CryptoBase.h"

/* Test values:
 * ""                  D4 1D 8C D9 8F 00 B2 04  E9 80 09 98 EC F8 42 7E
 * "a"                 0C C1 75 B9 C0 F1 B6 A8  31 C3 99 E2 69 77 26 61
 * "abc                90 01 50 98 3C D2 4F B0  D6 96 3F 7D 28 E1 7F 72
 * "message digest"    F9 6B 69 7D 7C B7 93 8D  52 5A 2F 31 AA F1 61 D0
 */

namespace Crypto
{
//#define  WORDS_BIGENDIAN

class md5
{
protected:
    u32 _A, _B, _C, _D;    // chaining variables
    u32  _nblocks;      // max digest size is limited to 64 * 4G
    int  _count;
    u8 _buf[64];

    const u32 rol (const u32 x, const unsigned int n) const  { return ( ((x) << (n)) | ((x) >> (32-(n))) ); }

    void copy_u32 (u32& dest, const u32 src)
    {
#ifdef WORDS_BIGENDIAN
        dest =   ( ((src&0x000000FF) << 24) | ((src&0x0000FF00) << 8) |
                 ((src&0x00FF0000) >> 8)  | ((src&0xFF000000) >> 24) );
#else
        dest = src;
#endif
    }
  
    /* These are the four functions used in the four steps of the MD5 algorithm
       and defined in the RFC 1321.  The first function is a little bit optimized
       (as found in Colin Plumbs public domain implementation).  */
    /* #define FF(b, c, d) ((b & c) | (~b & d)) */
    const u32 FF(const u32 b, const u32 c, const u32 d) const {    return (d ^ (b & (c ^ d))); }
    const u32 FG(const u32 b, const u32 c, const u32 d) const { return  FF (d, b, c);    }
  
    const u32 FH(const u32 b, const u32 c, const u32 d) const { return (b ^ c ^ d);        }
    const u32 FI(const u32 b, const u32 c, const u32 d) const { return (c ^ (b | ~d));    }

    void round1(u32& a, const u32 b, const u32 c, const u32 d, const u32 Xk, const u32 s, const u32 Ti) {
        a += FF (b, c, d) + Xk + Ti;
        a = rol(a, s);
        a += b;
    }

    void round2(u32& a, const u32 b, const u32 c, const u32 d, const u32 Xk, const u32 s, const u32 Ti) {
        a += FG(b, c, d) + Xk + Ti;
        a = rol(a, s);
        a += b;
    }

    void round3(u32& a, const u32 b, const u32 c, const u32 d, const u32 Xk, const u32 s, const u32 Ti) {
        a += FH(b, c, d) + Xk + Ti;  
        a = rol(a, s);
        a += b;
    }

    void round4(u32& a, const u32 b, const u32 c, const u32 d, const u32 Xk, const u32 s, const u32 Ti) {
        a += FI(b, c, d) + Xk + Ti;  
        a = rol(a, s);
        a += b;
    }

    /****************
     * transform 64 bytes
     */
    void transform (const void* const data )
    {
      
        u32 A = _A;
        u32 B = _B;
        u32 C = _C;
        u32 D = _D;

#ifdef WORDS_BIGENDIAN
        u32 correct_words[16];
        const u32 * const src = reinterpret_cast(data);
        for(size_t n=0; n<16; n++) {
            copy_u32(correct_words[n], src[n]);
        }
#else
        const u32* const correct_words = reinterpret_cast(data);
#endif
  
        // Before we start, one word about the strange constants.
        // They are defined in RFC 1321 as
        // T[i] = (int) (4294967296.0 * fabs (sin (i))), i=1..64
      
        round1 (A, B, C, D, correct_words[0],  7,  0xd76aa478);
        round1 (D, A, B, C, correct_words[1],  12, 0xe8c7b756);
        round1 (C, D, A, B, correct_words[2],  17, 0x242070db);
        round1 (B, C, D, A, correct_words[3],  22, 0xc1bdceee);
        round1 (A, B, C, D, correct_words[4],  7,  0xf57c0faf);
        round1 (D, A, B, C, correct_words[5],  12, 0x4787c62a);
        round1 (C, D, A, B, correct_words[6],  17, 0xa8304613);
        round1 (B, C, D, A, correct_words[7],  22, 0xfd469501);
        round1 (A, B, C, D, correct_words[8],  7, 0x698098d8);
        round1 (D, A, B, C, correct_words[9],  12, 0x8b44f7af);
        round1 (C, D, A, B, correct_words[10], 17, 0xffff5bb1);
        round1 (B, C, D, A, correct_words[11], 22, 0x895cd7be);
        round1 (A, B, C, D, correct_words[12], 7, 0x6b901122);
        round1 (D, A, B, C, correct_words[13], 12, 0xfd987193);
        round1 (C, D, A, B, correct_words[14], 17, 0xa679438e);
        round1 (B, C, D, A, correct_words[15], 22, 0x49b40821);
  
        round2 (A, B, C, D, correct_words[1],  5,  0xf61e2562);
        round2 (D, A, B, C, correct_words[6],  9,  0xc040b340);
        round2 (C, D, A, B, correct_words[11], 14, 0x265e5a51);
        round2 (B, C, D, A, correct_words[0],  20, 0xe9b6c7aa);
        round2 (A, B, C, D, correct_words[5],  5,  0xd62f105d);
        round2 (D, A, B, C, correct_words[10], 9,  0x02441453);
        round2 (C, D, A, B, correct_words[15], 14, 0xd8a1e681);
        round2 (B, C, D, A, correct_words[4],  20, 0xe7d3fbc8);
        round2 (A, B, C, D, correct_words[9],  5,  0x21e1cde6);
        round2 (D, A, B, C, correct_words[14], 9,  0xc33707d6);
        round2 (C, D, A, B, correct_words[3],  14, 0xf4d50d87);
        round2 (B, C, D, A, correct_words[8],  20, 0x455a14ed);
        round2 (A, B, C, D, correct_words[13], 5,  0xa9e3e905);
        round2 (D, A, B, C, correct_words[2],  9,  0xfcefa3f8);
        round2 (C, D, A, B, correct_words[7],  14, 0x676f02d9);
        round2 (B, C, D, A, correct_words[12], 20, 0x8d2a4c8a);
  
        round3 (A, B, C, D, correct_words[ 5],  4, 0xfffa3942);
        round3 (D, A, B, C, correct_words[ 8], 11, 0x8771f681);
        round3 (C, D, A, B, correct_words[11], 16, 0x6d9d6122);
        round3 (B, C, D, A, correct_words[14], 23, 0xfde5380c);
        round3 (A, B, C, D, correct_words[ 1],  4, 0xa4beea44);
        round3 (D, A, B, C, correct_words[ 4], 11, 0x4bdecfa9);
        round3 (C, D, A, B, correct_words[ 7], 16, 0xf6bb4b60);
        round3 (B, C, D, A, correct_words[10], 23, 0xbebfbc70);
        round3 (A, B, C, D, correct_words[13],  4, 0x289b7ec6);
        round3 (D, A, B, C, correct_words[ 0], 11, 0xeaa127fa);
        round3 (C, D, A, B, correct_words[ 3], 16, 0xd4ef3085);
        round3 (B, C, D, A, correct_words[ 6], 23, 0x04881d05);
        round3 (A, B, C, D, correct_words[ 9],  4, 0xd9d4d039);
        round3 (D, A, B, C, correct_words[12], 11, 0xe6db99e5);
        round3 (C, D, A, B, correct_words[15], 16, 0x1fa27cf8);
        round3 (B, C, D, A, correct_words[ 2], 23, 0xc4ac5665);
  
        round4 (A, B, C, D, correct_words[ 0],  6, 0xf4292244);
        round4 (D, A, B, C, correct_words[ 7], 10, 0x432aff97);
        round4 (C, D, A, B, correct_words[14], 15, 0xab9423a7);
        round4 (B, C, D, A, correct_words[ 5], 21, 0xfc93a039);
        round4 (A, B, C, D, correct_words[12],  6, 0x655b59c3);
        round4 (D, A, B, C, correct_words[ 3], 10, 0x8f0ccc92);
        round4 (C, D, A, B, correct_words[10], 15, 0xffeff47d);
        round4 (B, C, D, A, correct_words[ 1], 21, 0x85845dd1);
        round4 (A, B, C, D, correct_words[ 8],  6, 0x6fa87e4f);
        round4 (D, A, B, C, correct_words[15], 10, 0xfe2ce6e0);
        round4 (C, D, A, B, correct_words[ 6], 15, 0xa3014314);
        round4 (B, C, D, A, correct_words[13], 21, 0x4e0811a1);
        round4 (A, B, C, D, correct_words[ 4],  6, 0xf7537e82);
        round4 (D, A, B, C, correct_words[11], 10, 0xbd3af235);
        round4 (C, D, A, B, correct_words[ 2], 15, 0x2ad7d2bb);
        round4 (B, C, D, A, correct_words[ 9], 21, 0xeb86d391);
  
        // Put checksum in context given as argument.
        _A += A;
        _B += B;
        _C += C;
        _D += D;
    }
  
public:
    void start()
    {
        _A = 0x67452301;
        _B = 0xefcdab89;
        _C = 0x98badcfe;
        _D = 0x10325476;
  
        _count = 0;
        _nblocks = 0;
    }

    void update(const void* const inbuf_arg , size_t inlen)
    {
        const unsigned char* inbuf = (const unsigned char *)inbuf_arg;
        if( !inbuf  || !inlen ) {
            return;
        }

        assert(_count < 64);
        if( _count ) {
            for( ; inlen && _count < 64; inlen-- ) {
                _buf[_count++] = *inbuf++;
            }
            if(_count == 64) {
                transform( _buf);
                _count = 0;
                _nblocks++;
            }
        }

        while( inlen >= 64 ) {
            assert(_count == 0);
            transform(inbuf );
            _count = 0;
            _nblocks++;
            inlen -= 64;
            inbuf += 64;
        }
        for( ; inlen && _count < 64; inlen-- ) {
            _buf[_count++] = *inbuf++;
        }
    }

    u8 *end()
    {
        u32 t, len_h, len_l;

        // multiply by 64, than 8  to make a bit count
        len_l = _nblocks << (6 + 3);
        len_h = _nblocks >> (32 - 6 - 3);
  
        // add the count
        t = len_l;
        if( (len_l += (_count << 3)) < t ) {
            len_h++;
        }

        if( _count < 56 )  {// enough room
            _buf[_count++] = 0x80; /* pad */
            while(_count < 56 )
                _buf[_count++] = 0;  /* pad */
        } else  { // need one extra block
            _buf[_count++] = 0x80; /* pad character */
            while( _count < 64 )
                _buf[_count++] = 0;
            transform( _buf); // _count = 0; _nblocks++;
            memset(_buf, 0, 56 ); // fill next block with zeroes
        }

        // append the 64 bit count
        _buf[56] = len_l       ;
        _buf[57] = len_l >>  8;
        _buf[58] = len_l >> 16;
        _buf[59] = len_l >> 24;
        _buf[60] = len_h       ;
        _buf[61] = len_h >>  8;
        _buf[62] = len_h >> 16;
        _buf[63] = len_h >> 24;
        transform( _buf );
      
        u32* md5 = reinterpret_cast(_buf);
        copy_u32(md5[0], _A);
        copy_u32(md5[1], _B);
        copy_u32(md5[2], _C);
        copy_u32(md5[3], _D);
      
        return _buf;
    }

    static u32 digest_size() { return 4; }

    static std::string get_str(const u8* const md5_buf, const Base::StrType str_type = Base::StrHex)
    {
        std::string str, sub_str;
        if(md5_buf) {
            Base::to_str(str, reinterpret_cast(md5_buf), digest_size(), str_type);
        }
      
        return str;
    }
  
    // handy tools
    u8 *digest(std::ifstream& is)
    {
        if(is.good()) {
            start();
            const int buff_size = 64 * 16; // 1K
            char buffer[buff_size];
            std::streamsize length;
            while (!is.eof()) {
                is.read(buffer, buff_size);
                length = is.gcount();
                if (length > 0) {
                    update(buffer, length);
                }
            }
            return end();
        }
        return NULL;
    }
};

} // namespace Crypto

#endif //#ifndef _MD5_H_